
Key takeaway
For each endpoint, define identity checks, object-level authorization, the accepted schema and which sensitive data must stay out of the response.
What an endpoint defines
An API lets programs exchange data and perform operations under defined rules. An endpoint is the URL for a resource on a server or service together with the method applied to it: a client sends a request and the service returns a response. For example, GET /accounts/{id} may read an account and POST /payments may create a payment. Knowing the URL does not grant access.
Resource
Defines the data or operation being addressed.
Identity and authorization
Checks who sent the request and what they may do with the resource.
Response
Returns only required data and does not expose internal configuration or secrets.
Separate /health and /info endpoints
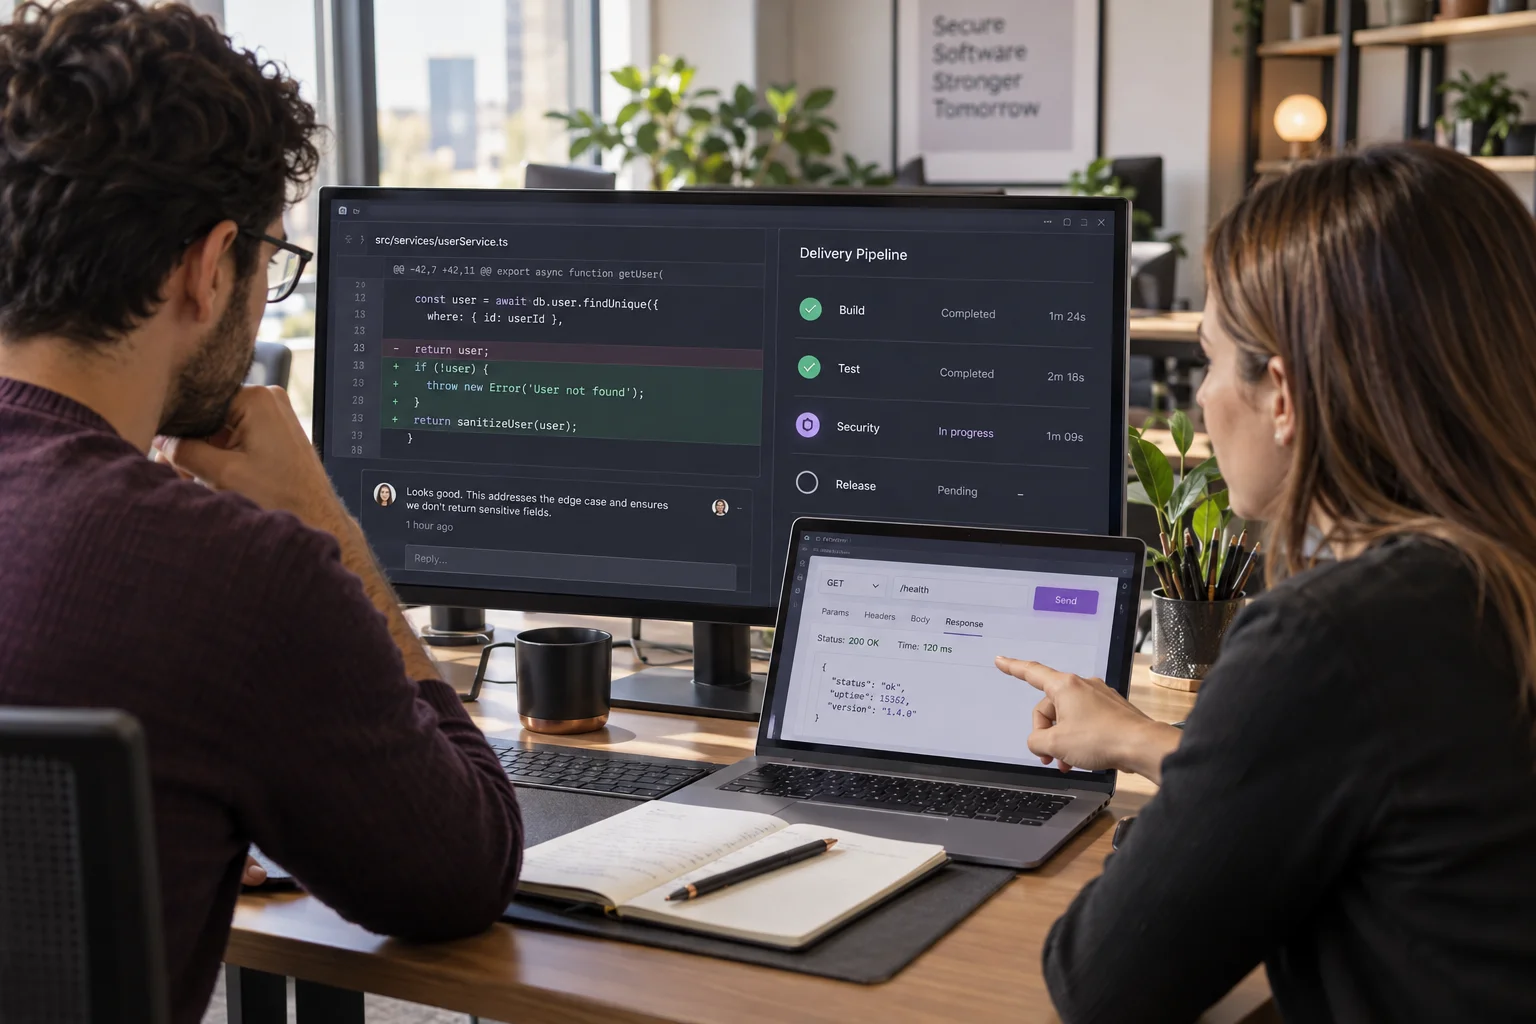
/health usually provides a brief signal about whether a process or service is running; an orchestrator or monitor may use it to decide readiness or restart behavior. In Kubernetes, a container restarts when failed liveness probes reach the configured threshold, while readiness excludes an unready pod from new traffic routed through a Kubernetes Service. Readiness is not a network security rule that blocks all access to the pod. /info may expose application version and build metadata. The names do not guarantee standard behavior: you control the content, access level and network scope. Keep secrets, environment variables, internal addresses, exact component versions and sensitive dependency status out of public responses; minimize diagnostic detail and require authentication where appropriate.
Strong authentication and object-level authorization
Require HTTPS for all API traffic. Verify user or service identity with an appropriate mechanism; limit token lifetime, audience and scope, and keep secrets out of source control. Recheck authorization on the server for the specific object and operation in every request: authenticating a user does not grant access to another account or an administrative function. Give services separate identities and the minimum permissions they need.
Protect inputs and database queries
Validate request size, content type and schema on the server, with explicit rules for accepted fields and formats. Do not build SQL by concatenating user text. Parameterized queries keep values separate from SQL code and are the primary defense against SQL injection. Input validation is useful as another layer, but does not replace parameterization. Give the database account only the tables and operations it needs, hide detailed error messages from users, and store passwords with an appropriate slow salted hash.
Limit resource use and test endpoints
Limit request frequency as well as pagination, body size, and the cost of expensive search and export operations. Account for pre- and post-authentication cases and usage per account or key; an IP-only limit may not stop distributed bots. Keep personal data, tokens and passwords out of logs while retaining enough events for detection under a defined retention and access policy. Test invalid tokens, another user’s object ID, extra fields, oversized payloads, SQL syntax and limit enforcement. Confirm that response codes, latency, errors and blocking behavior match expectations.